Models Library & Speech Engine
Explore local Whisper GGUFs, Cloud ASR, LLM refinement, quantization, and RAM optimization.
Dicty features a modular AI architecture supporting on-device hardware-accelerated models and ultra-accurate cloud intelligence.
Local Speech Models (ASR)#
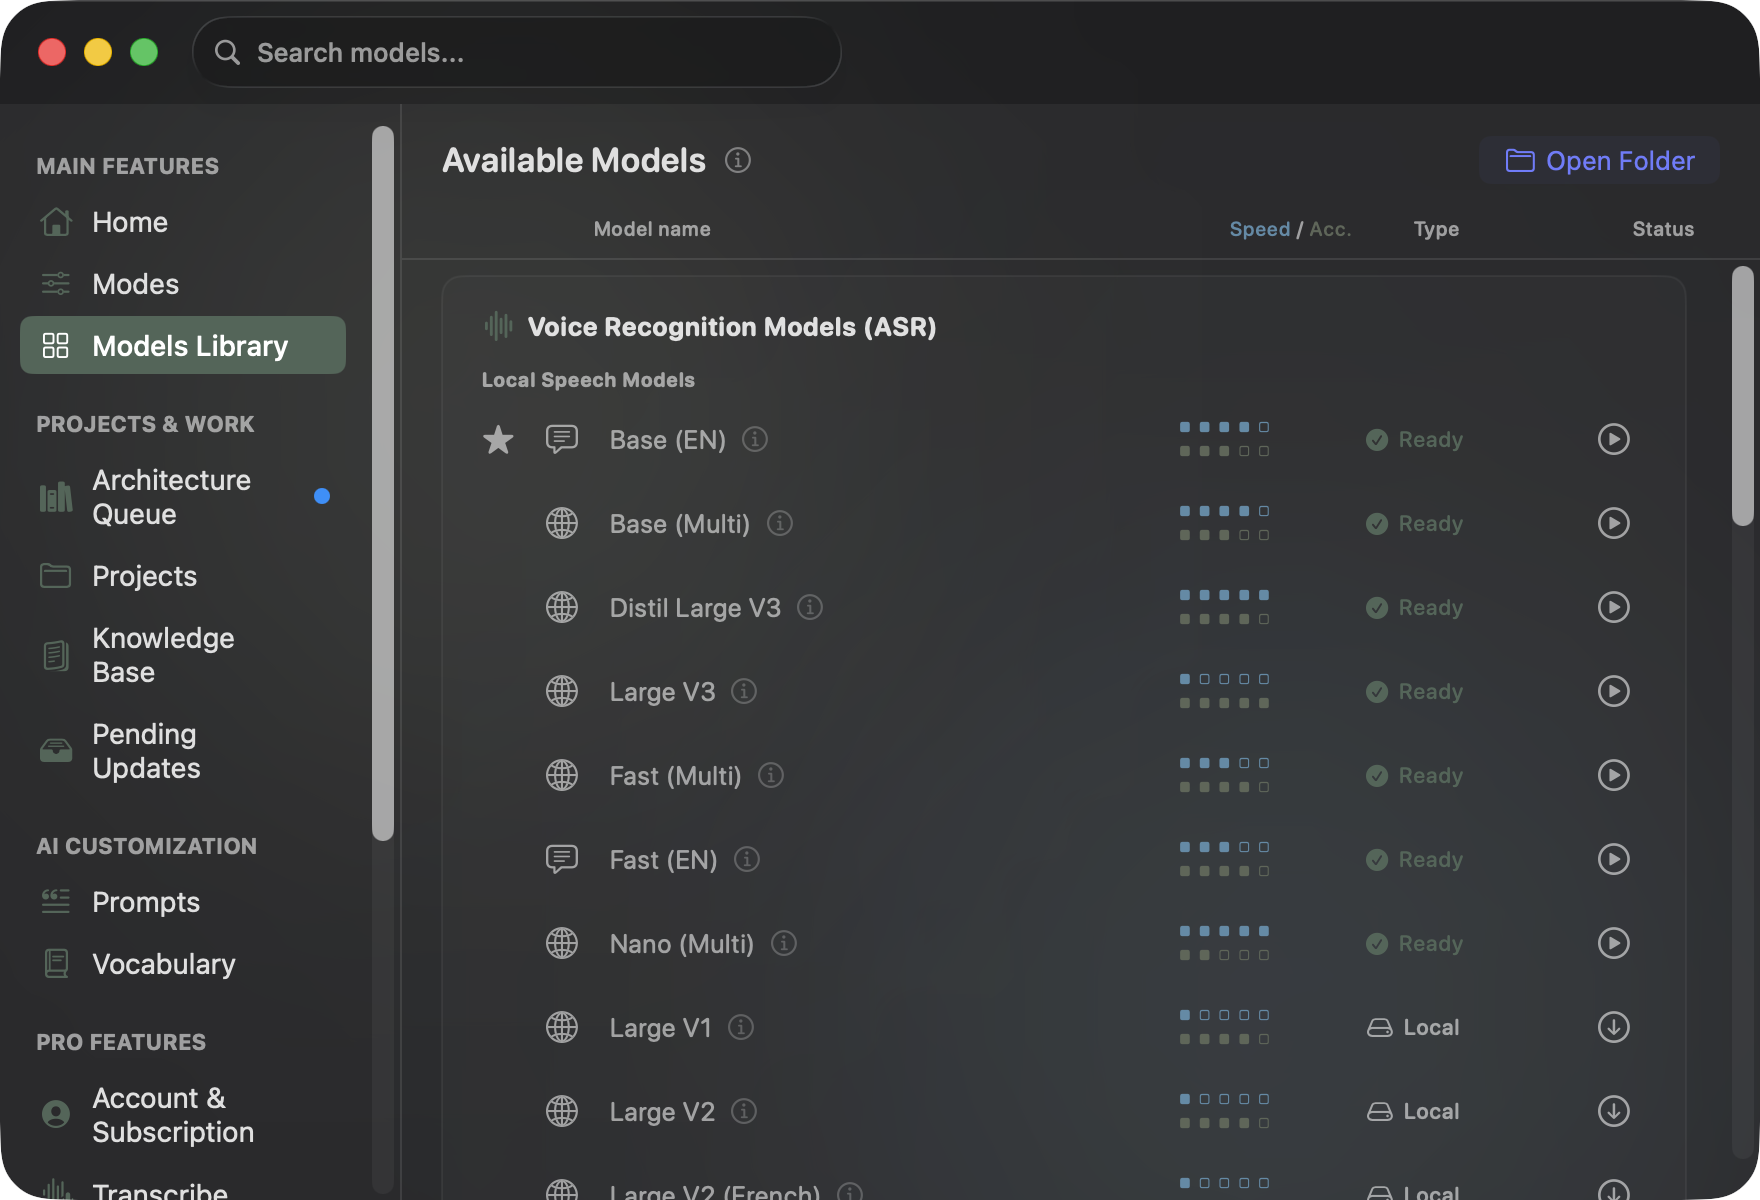
Local models run 100% offline on your Mac using whisper.cpp optimized with Apple Metal GPU shaders.
| Model | Size | Speed | Accuracy | Best Used For |
|---|---|---|---|---|
| Nano (EN / Multi) | ~75 MB | ⚡️⚡️⚡️ 1.0 | ★★☆☆☆ (0.4) | Ultra-light background typing on older machines. |
| Base (EN / Multi) | ~140 MB | ⚡️⚡️⚡️ 0.8 | ★★★☆☆ (0.6) | Fast baseline for clear speakers. |
| Fast (EN / Multi) | ~460 MB | ⚡️⚡️ 0.6 | ★★★★☆ (0.8) | Sweet spot: Fast response and high everyday accuracy. |
| Pro (EN / Multi) | ~1.5 GB | ⚡️ 0.4 | ★★★★★ (0.9) | Complex technical vocabulary and code names. |
| Large V3 Turbo | ~1.6 GB | ⚡️⚡️ 0.8 | ★★★★★ (0.98) | Recommended: Near Large V3 accuracy at 4x inference speed. |
| Large V3 | ~3.1 GB | ⚡️ 0.2 | ★★★★★ (1.0) | Studio-grade acoustic precision and heavy accents. |
| Distil Large V3 | ~1.5 GB | ⚡️⚡️⚡️ 1.0 | ★★★★★ (0.98) | Distilled model for English dictation. |
Model Specifications & Quality Inspection#
Click the info badge next to any installed speech model to inspect its technical profile, installed quantization tier, and relative benchmarking stats:
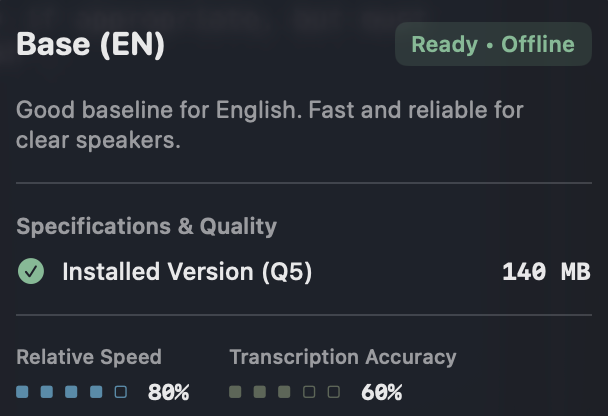
- Status Indicator: Shows
Ready • Offlinewhen the weights are validated and available for instant offline transcription. - Installed Version: Displays active disk footprint (e.g.,
140 MBfor Base Q5). - Benchmark Gauges: Visual meters for real-time inference speed (e.g.,
80%) and acoustic accuracy (e.g.,60%).
Specialized Regional Models#
- BELLE (Chinese - 3.1 GB): Fine-tuned for Mandarin and Chinese dialects.
- Large V2 (French - 3.1 GB): Trained on thousands of hours of French audio to resolve silent letter ambiguities.
- Large V3 Turbo (Japanese - 1.6 GB): Fine-tuned to eliminate Japanese hallucinations.
Understanding Quantization & Download Tiers#
When downloading local models from the library, Dicty provides three precision profiles tailored for different hardware setups:
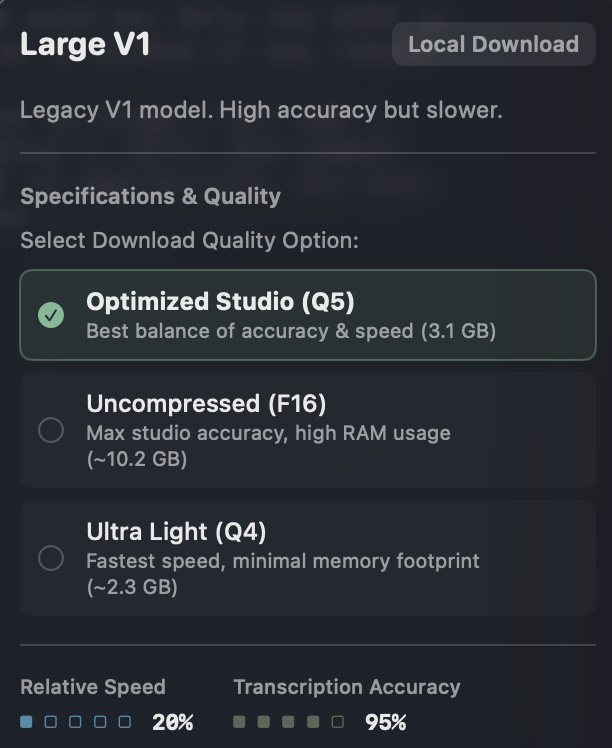
- Optimized Studio (Q5) — Recommended:
- Retains ~99% of full 16-bit acoustic accuracy while cutting memory and disk requirements by 50% (e.g.
3.1 GBfor Large V1/V3). - Provides optimal performance on Apple Silicon unified memory (M1 or later).
- Retains ~99% of full 16-bit acoustic accuracy while cutting memory and disk requirements by 50% (e.g.
- Uncompressed (F16) — Maximum Precision:
- 16-bit uncompressed floating-point weights (~
10.2 GB). - Best for studio environments, heavy background noise, or subtle phoneme distinctions.
- 16-bit uncompressed floating-point weights (~
- Ultra Light (Q4) — Minimal Footprint:
- 4-bit integer weights (~
2.3 GB). - Blazing-fast inference speed and minimal battery usage for laptop multitasking.
- 4-bit integer weights (~
LLM Text Refinement & Advanced Model Settings#
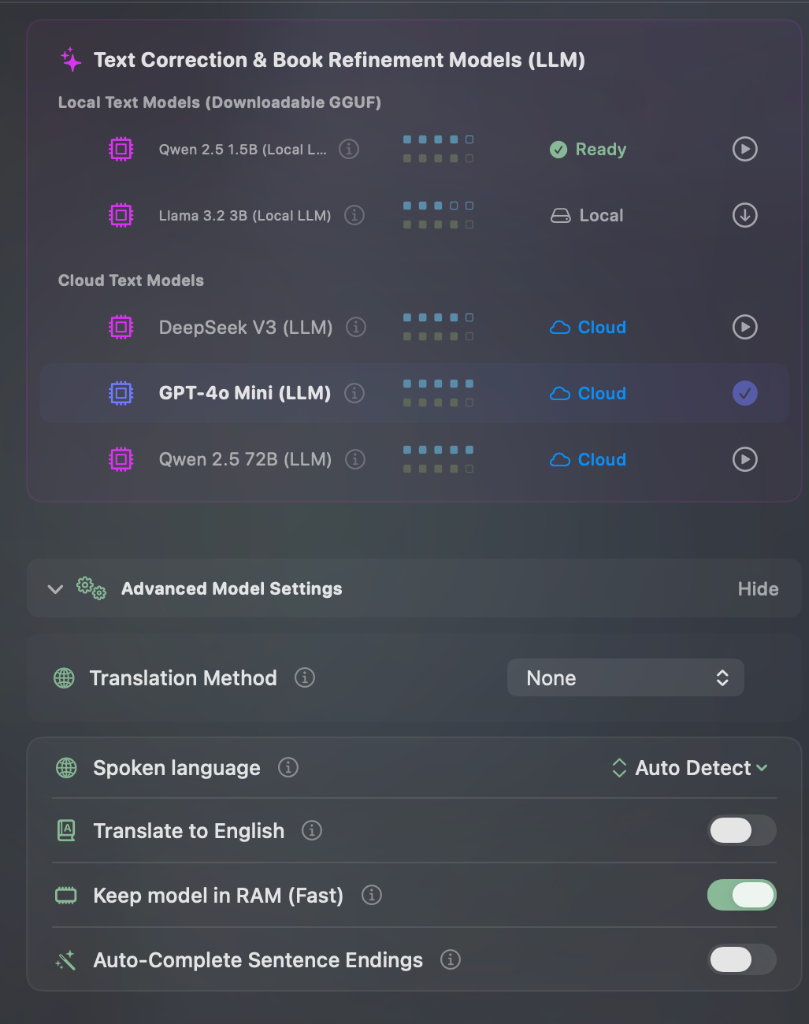
Dicty pairs raw speech recognition with local and cloud Large Language Models to format book prose, remove verbal disfluencies, and draft structured notes:
LLM Text Refinement Models#
- Local GGUF Models: Download and run lightweight instruction models locally (e.g. Qwen 2.5 1.5B for fast offline punctuation, Llama 3.2 3B for comprehensive editing).
- Cloud LLMs: Connect to top-tier reasoning engines (DeepSeek V3, GPT-4o Mini, Qwen 2.5 72B, Claude 3.5 Sonnet) with one click.
Advanced Model Settings#
| Control Setting | Configurable Options | Functional Description |
|---|---|---|
| Translation Method | None / Built-in / LM Studio / Cloud | Selects whether translation uses on-device Whisper, local LM Studio, or cloud LLMs. |
| Spoken Language | 90+ Languages / Auto Detect | Supports 90+ languages (English, Spanish, German, French, Japanese, Russian, Ukrainian, Chinese, etc.). Explicitly selecting your language improves speed and accuracy over Auto Detect. |
| Translate to English | Toggle ON / OFF | Directly translates spoken foreign language audio into fluent English text during transcription. |
| Keep model in RAM (Fast) | Toggle ON / OFF | Keeps speech recognition weights warm in Apple Silicon unified memory for zero-latency startup. Disable on 8GB RAM Macs to conserve system memory. |
| Auto-Complete Sentence Endings | Toggle ON / OFF | Uses acoustic context to predict sentence endings and suppresses common Whisper silence hallucinations. |